Research note · cuDNN · PyTorch

The cuDNN bug that breaks training at scale.

While we were training an image model we simply changed how batches were split, and the model stopped learning. Even more, it started to unlearn. The cause: a newly discovered cuDNN bug in how it calculates a 32-bit address in the attention backward. Past 4 GiB it wraps, and the kernel reads the wrong memory with no error. Here is how we found it, who it affects, and how to check your own runs.

Speridlabs — Alex GarabitocuDNN 9.10 – 9.27
FIG. 00
FIG. 00 · The bug, in 30 secondsno audio

01 — The run

The model stopped learning.

While I was training an image model on B300 GPUs, a run that had been stable for quite some time, I decided to test a change in the batching: smaller microbatches with gradient accumulation, same global batch, same data, same seed. I did not expect anything to move. Mathematically, nothing should have.

Seven steps after the change the gradient norm, which had sat near 0.1 for the whole run, jumped ×1000 to 154, and at ten steps to 243. The loss, however, did not blow up. It went from about 0.70 to 0.90 and stayed around that value, noisy but finite. Nothing crashed, there was no NaN, the training metrics looked fine. My first assumption was that I had got the accumulation wrong and the effective learning rate had changed. It had not. Meanwhile, the further the steps got from the change, the more the model drifted, “unlearning” everything it knew before.

Getting suspicious, I restored the last good step and ran the same steps again with the old batch layout. Gradient norms stayed at 0.1 and the loss at 0.70. Same weights, same data, same seed; the only thing that had changed was how the batches sat in memory. Mathematically the two approaches are equivalent, so they should not drift that much between the two experiments. Back then I did not know yet that this was not a tuning problem. It was something deeper in the pyramid.

Shared parentDegraded branchCorrected rerunLayout changeLoss shift, +12
FIG. 01.A · Global training lossn = 1,055
0.60.70.80.91.01.1-1000+100+200+300+400STEPS SINCE THE LAYOUT CHANGEGLOBAL TRAINING LOSS
Raw observations faint, trailing 21-observation median bold. The rerun also restored data order, so these curves illustrate the incident; the controlled evidence is in 02 and 03.
FIG. 01.B · Gradient norm before clippingsymlog · linthresh 0.05
00.1110100-1000+100+200+300+400STEPS SINCE THE LAYOUT CHANGEGRADIENT NORM · SYMLOG
Every point raw. First amplified gradient seven steps after the change (154.35), peak at ten (243.22). The corrected rerun stays near 0.1 for the following 437 steps.
FIG. 01.C · The onset−20 to +80 steps
00.1110100-200+20+40+60+80+10 steps: 243.22first spike at +7: 154.35STEPS SINCE THE LAYOUT CHANGEGRADIENT NORM · SYMLOG
Loss and gradient are measured before each step; a step cannot cause its own already-measured gradient.

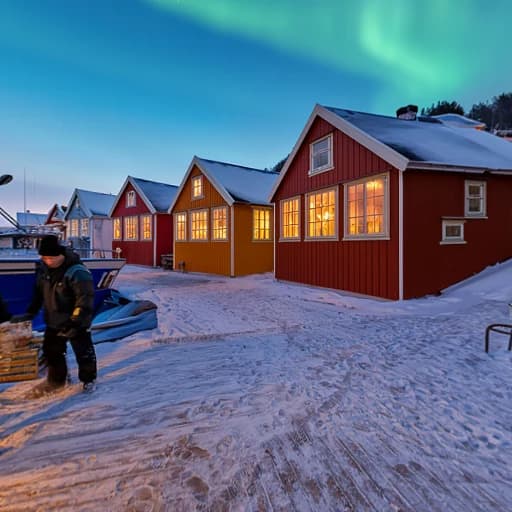
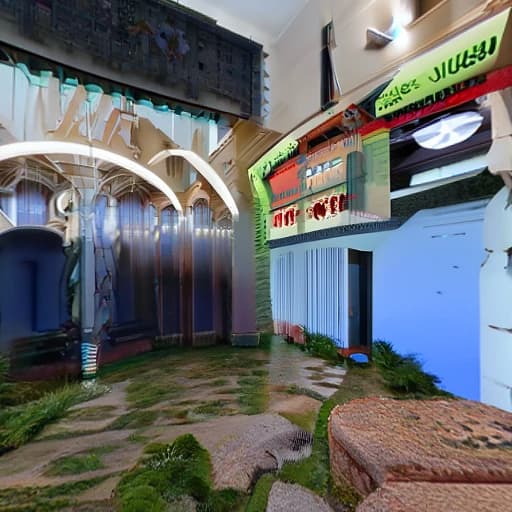
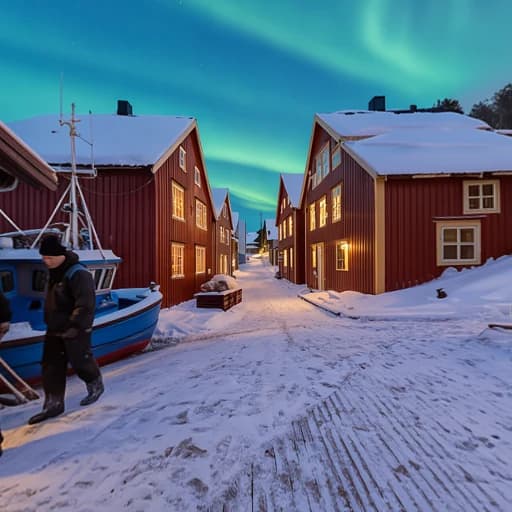
FIG. 01.D · Model outputs · same prompt and seed

View
Before, last good step
Beforelast good step
Degraded, +295 steps
Degraded+295 steps
Corrected rerun, +219 steps
Corrected rerun+219 steps

The corrected image comes from the rerun restored at the last good step, not from a continuation of the degraded branch.

02 — Narrowing it down

Same math, four answers.

I decided to dissect the forward and backward passes, so I took the weights from the last good step, froze a batch of inputs, and recomputed every layer’s gradient against an FP64 reference. The forward pass matched bitwise. In the attention backward, dV matched. dQ and dK did not: in one batch they were off by 17×.

That pointed at the attention calculation, which made it even stranger: one always relies on the good old kernel and library developers, who are surely smarter than me. So, in my personal paranoia, I computed the same gradient four ways: cuDNN on the batch as delivered, cuDNN one example at a time, FlashAttention on the batch, and cuDNN on the batch with the incoming gradient copied into a contiguous buffer first. Three agreed to three digits. The first was 1,200× larger. The arithmetic was identical in all four; the only thing that differed was where the bytes sat in memory. By then I was fairly sure the kernel was reading data from the wrong address. Without an answer to where or why, my good friend Astra and I decided to dig deeper into the problem.

FIG. 02.A · Controlled backward replaylog scale · one parameter
0.111010088.179cuDNNstrided, batch 20.071049cuDNNindividual examples0.070392FlashAttentionbatch 20.070973cuDNNpacked upstream gradientWEIGHT GRADIENT NORM · LOG
H200, BF16, weights from the last good step, fixed inputs, no optimizer step. Gradient norm of one time-MLP weight. Packing preserves the forward values bitwise.

03 — Root cause

One instruction.

With Astra I reverse-engineered the cuDNN library loaded in my training environment and went looking for the code responsible for my faulty model: we captured the kernel’s launch arguments with CUPTI, extracted the cubin from the running process and disassembled it. The bug is a simple one. It sits in the address arithmetic of the kernel that computes the dot product D = sum(O ⊙ dO) for the attention backward, compute_dot_do_o_specialized<true,128> in libcudnn_engines_runtime_compiled.so.9. One instruction.

A memory address is a number. This kernel keeps part of that number in a 32-bit register, which counts up to 4,294,967,295 bytes: 4 GiB. One byte further and it rolls over to zero. From there on the kernel reads from the start of the tensor instead of where it should.

FIG. 03.A · Address wraparounduint32 · 2³² = 4 GiB
04 GiB · 2³²8 GiB
intended
actual read
64-bit offset0000000100100000000000000000000000000000uint32 keeps0000000100100000000000000000000000000000Kernel reads at536,870,912 B — 4 GiB before the intended cell, inside the same allocation.

These are the four instructions, straight from the official cuobjdump. The first one does the damage: it multiplies the element offset by the element size into a 32-bit register and drops the high bits. The next two add the base pointer in 64 bits, correctly, and the fourth loads from the wrapped address.

FIG. 03.B · Four instructions, sm_90a · cuobjdump
0x0e80  IMAD.SHL.U32  R17, R12, 0x2, RZ             ; 32-bit shift. bits lost0x0ee0  IADD3         R16, P1, R17, R8, RZ          ; base, low word0x0ef0  IMAD.X        R17, RZ, RZ, R9, P1           ; base, high word, carry0x0f10  LDG.E.128.CONSTANT R12, desc[UR8][R16.64]   ; load from wrapped address

Why a tensor crosses 4 GiB without anyone noticing. This was the part that surprised me most. A tensor’s logical size and its physical footprint are different numbers. The reproducer I ended up with uses 131 KB of data delivered through a strided view with a batch stride of 2,147,467,264 elements, so batch 1 sits past the 4-GiB line and batch 0 before it. Same values, same shape, same dtype. The backward of torch.cat, one of the most common ops in multi-branch models, produces exactly these views. That is exactly what my batching change had done to the incoming gradient.

FIG. 03.C · Python · illustrative excerpt
backing  = torch.full((stride + 32768,), 0.0, device='cuda', dtype=torch.bfloat16)upstream = backing.as_strided((2, 256, 1, 128), (2147467264, 128, 128, 1))# logical size: 2*256*128*2 B = 131,072 B   physical span: 4,295,000,064 B
Illustrative excerpt, not a standalone script. Batch 1 crosses byte offset 2³² at token 128.

To be sure we were not fooling ourselves, we patched a research copy of the binary. Widening that one instruction (IMAD.WIDE) drops the error from 0.5726 to 4.35×10⁻⁸ and makes the output bitwise identical to the packed control across 6,365,184 rows. Two bytes of SASS.

04 — Who is affected

It depends on the wheel you installed.

PyTorch chooses the attention kernel for you. On the CUDA 13 wheel (cu130) the default is cuDNN, and the crossing case fails with no configuration at all. On the CUDA 12 wheel (cu126) the default is FlashAttention, which is not affected. Honestly, I did not know which backend I was running until I checked, and I suspect most people do not either.

Head width does not help either: I tested 64, 128 and 256, and all three wrap on cuDNN 9.24 and later.

Same crossing layout, same H200. Only the wheel differs.FIG. 04.A

PyTorch buildDefault backendResult
2.14.1+cu130 · cuDNN 9.24cuDNN✗ fails silently
2.14.1+cu126 · cuDNN 9.10.2FlashAttention✓ passes

Beyond Hopper. The original failure happened on B300 GPUs, so we tested there, and then again on H200. Those are the two architectures where we executed the reproducer. To see how far this reaches beyond them, we disassembled the same kernel family in every cubin cuDNN 9.20 ships. The truncating instruction is there for A100, Ampere and the Blackwell consumer parts; B200 uses a different address chain. For those architectures this is static evidence, read from the binaries, not something we ran, so more architectures than the two we tested may be affected. We have asked NVIDIA to confirm it.

cuDNN 9.20 binaries. Executed means reproduced on hardware; static means inspected in the binary only.FIG. 04.B

ArchitectureVariantsTruncationEvidence
sm_103 · B300—PresentReproduced
sm_90a · H100 / H20030Present · 0x0e80Reproduced
sm_80 · A10014Present · 0x0cf0Static inspection
sm_86 · Ampere14PresentStatic inspection
sm_120 / 121 · Blackwell30Present · two sitesStatic inspection
sm_100 · B20030Different address chainNeeds testing
sm_89 · Ada—Uses sm_86 cubinInference
sm_75 · Turing—Kernel absent—

05 — What it looks like

The loss will not tell you.

To see how bad this is in practice, I trained a small model for 80 steps, with and without the bug. Final losses: 0.4453 and 0.4492. Had I only been watching the loss, I would have called them the same run. The learned weights differ by 172%.

The good news is that you can check a run without an FP64 reference, which is what I wish I had had from the start. Run the same backward twice, once with the upstream gradient made contiguous, and compare per batch. Below the boundary the divergence is exactly zero. On a crossing batch it is 0.128.

FIG. 05.A · Python · illustrative excerpt
grad_a = torch.autograd.grad(o, q, dO.contiguous())   # safegrad_b = torch.autograd.grad(o, q, gapped_dO)          # maybe wrapped# batch below boundary:  divergence exactly 0.0# batch crossing it:     divergence 0.128  <- your canary
Illustrative excerpt, not a standalone script. Measured: 0.0 below the boundary; dQ 0.1285 / dK 0.1011 on the crossing batch.

06 — Tooling

Why no tool caught it.

Before trusting any of this I ran the standard sanitizers on the failing case, expecting one of them to complain. None did. Memory checkers look for a program touching memory it does not own; this kernel reads inside your own tensor, just the wrong part of it. memcheck, initcheck and racecheck report the same thing for the broken case and the control.

And no test suite crosses 4 GiB per tensor. You need a multi-gigabyte strided layout and a build that defaults to cuDNN. Few teams are in that intersection, and a run that trains badly rarely gets written up. I doubt we were the first to hit this; we may just have been the first to keep pulling.

Wrapped crossing case vs packed control. synccheck did not complete in either run.FIG. 06.A

ToolWrappedControlDiscriminates?
memcheck0 errors0 errorsNo
initcheck20,48020,480No
racecheck0 hazards0 hazardsNo
synccheckIncompleteIncomplete—

07 — Security

The wrong bytes end up in the gradient.

Once I knew the kernel reads from the wrong place inside the allocation, the next question was whether those bytes could be recovered. They can. I planted a 128-byte pattern next to a tensor I controlled and read it back from the gradient byte for byte, with memcheck reporting zero errors. After freeing the tensor, the pattern was still recoverable through allocator reuse.

What this is: a same-process information-read primitive. If you control the layout and can read gradients — a third-party plugin, a fingerprinting attack, a tensor collision with secrets — the wrapped read carries bytes from adjacent memory into your gradient.

Classification. The defect matches CWE-190 (integer overflow or wraparound) as its mechanism and CWE-125 (out-of-bounds read) as its consequence: the read lands outside the intended buffer, inside the allocation. CWE-197 (numeric truncation) and CWE-681 (incorrect numeric conversion) describe the same operation more loosely.

08 — Fixing it

Three layers.

01 · Vendor kernel

The real fix

We have contacted NVIDIA to disclose the defect and the CWEs it matches, and to see what they consider the right patch. We suggested one: widen the arithmetic before every product and sum; validate descriptors; reject unsupported layouts before execution, and we handed them the exact instruction offsets. Fixing only the final byte calculation is not enough: an earlier 32-bit element-index step fails above 2³² elements.

02 · Framework guard

PyTorch guard

We have opened an issue in PyTorch and are waiting for their answer to submit a PR against it and mitigate the problem on their side. Meanwhile the patch is documented in our repo. The guard checks the byte span of O and dO before cuDNN’s backward. Over 4 GiB and packable: pack it, one copy. Not packable: refuse loudly. Measured cost 887.96 ms vs 887.51 ms per attention step, about 0.05%.

03 · Temporary fix

What you can do today

Simple to apply while a fix ships. The .contiguous()-and-compare check from section 05, or force SDPBackend.FLASH_ATTENTION until a fixed cuDNN ships.

09 — Reproducing it

One fingerprint, six versions.

The defect is deterministic, which made it much easier to argue. The batch-1 dQ error is the same number on every machine and every cuDNN version I tested, from 9.10 to 9.27. Controls pass: one step below the boundary, the same data packed, and the crossing layout with the guard.

H200 NVL · PyTorch 2.14.1+cu126 · driver 595.91.07.FIG. 09.A

cuDNN runtimeBuildCrossing case
9.10.2 · stock91002✗ fails
9.19.0.5691900✗ fails
9.20.0.4892000✗ fails
9.24.0.4392400✗ fails
9.26.1.192601✗ fails
9.27.0.4292700✗ fails