
Iris-3B
Pixel-space generation & general vision learner
Iris-3B is a pixel-space generative model that can act as a general vision learner. Working in pixel space, it bypasses the lossy compression and the biased, texture-focused latents of a VAE. We show image generators can replace vision models such as DINOv2, release our pixel-space scaling recipes, and put the generative prior to work on dense tasks where detail matters.
Hanqiu Li Cai†Chema GarabitoSperidlabs · † project lead
Gallery
Architecture
A 3B flow-matching transformer that generates raw RGB pixels directly, with no VAE in the loop.
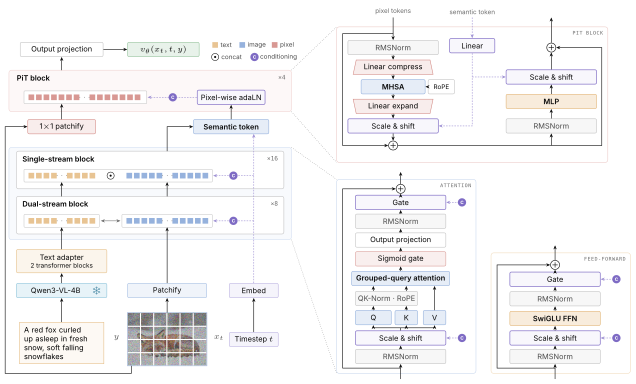
Images are cut into 16 × 16 pixel patches. The trunk has 8 dual-stream blocks, with separate text and image weights, followed by 16 single-stream blocks.
A small pixel-transformer (PiT) head decodes each patch token back to pixels. Text comes from a frozen Qwen3-VL-4B encoder, and 2D RoPE lets one set of weights run at any resolution and aspect ratio up to one megapixel.
Benchmarks
Competitive with state-of-the-art latent models on every official benchmark, at a fraction of their training compute.
| Model | GenEval | DPG | LongText | OneIG |
|---|---|---|---|---|
| SDXL | — | 74.65 | — | 0.316 |
| SD3 Medium | 0.62 | 84.08 | — | — |
| FLUX.1-dev 12B | 0.66 | 83.8 | 0.607 | 0.434 |
| SD3.5 Large | 0.71 | — | — | 0.462 |
| Lumina-Image 2.0 | 0.73 | 87.20 | — | 0.353 |
| Janus-Pro-7B | 0.80 | 84.19 | 0.019 | 0.267 |
| HiDream-I1-Full | 0.83 | 85.89 | 0.543 | 0.477 |
| Z-Image 6B* | 0.84 | 88.1 | 0.935 | 0.546 |
| Qwen-Image 20B | 0.87 | 88.3 | 0.943 | 0.539 |
| Iris-3B | 0.798 | 86.52 | 0.857 | 0.540 |
Iris-3B: official evaluators at 1024², no prompt rewriting, no best-of-N. References from the Qwen-Image and Z-Image reports; — not reported; * uses prompt rewriting.
Downstream
Iris-3B tuned for downstream tasks.
Depth
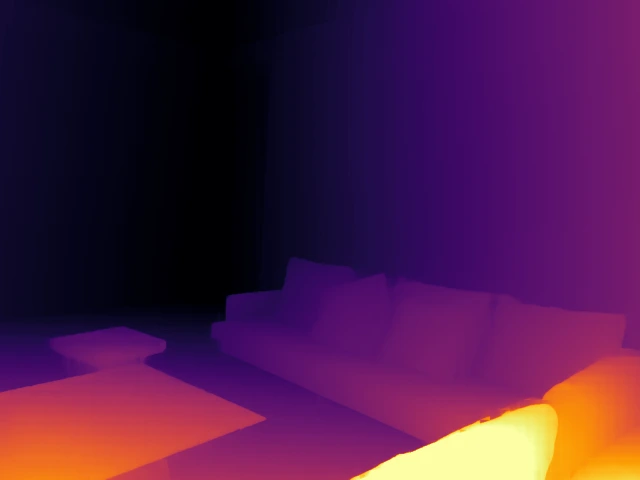
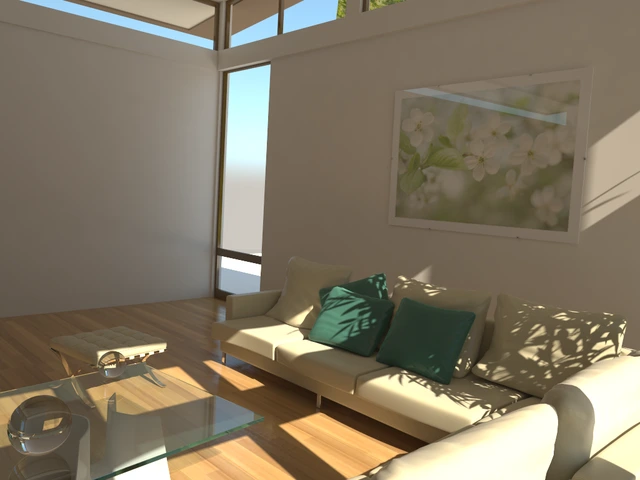 PhotoDepth
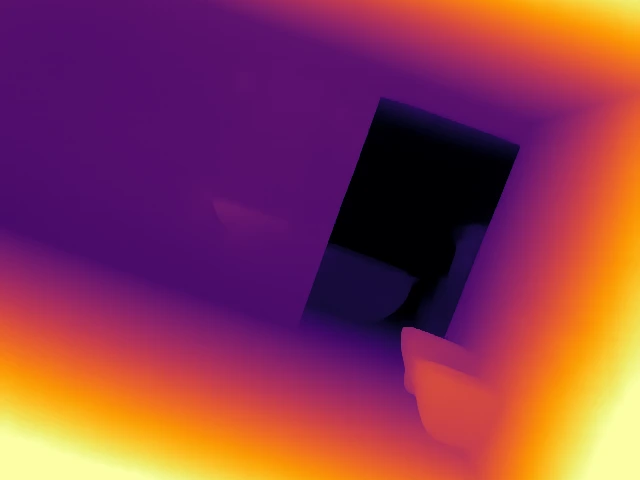
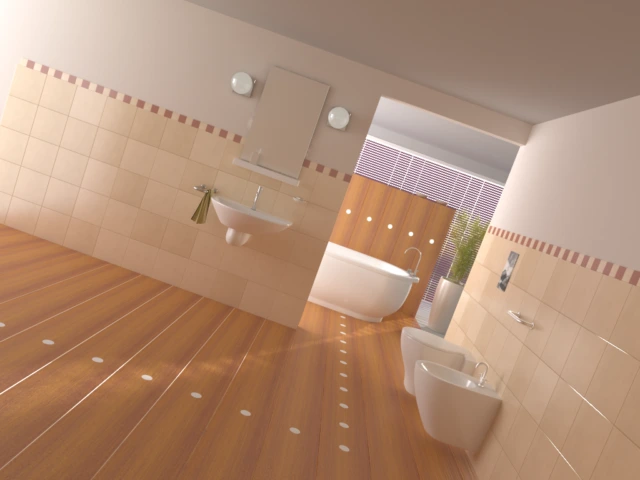 PhotoDepth
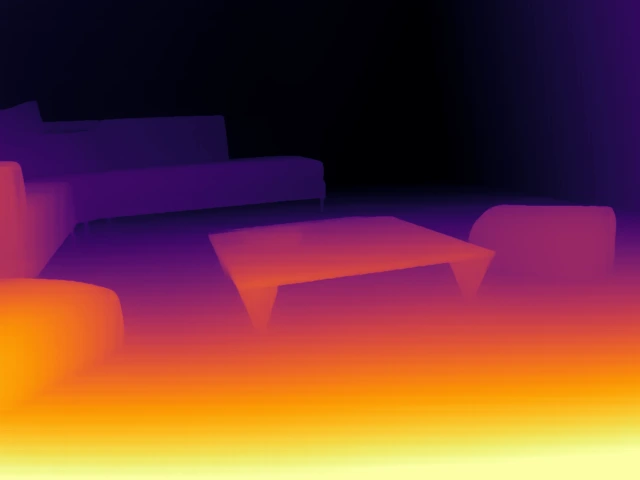
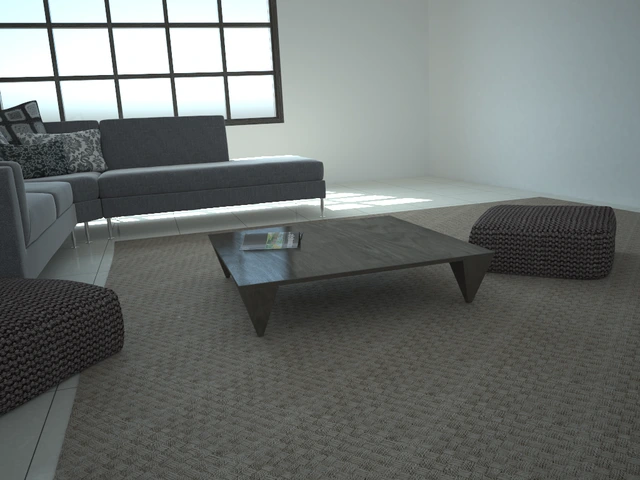 PhotoDepth
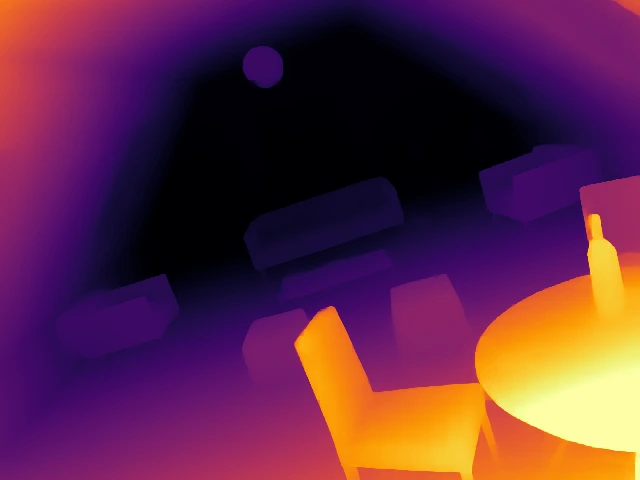
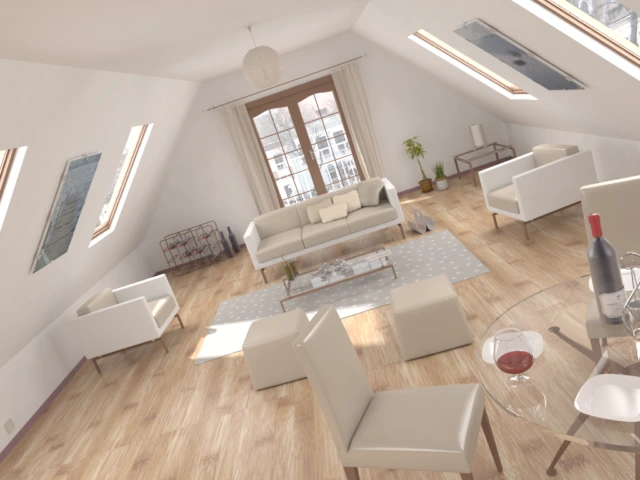 PhotoDepth
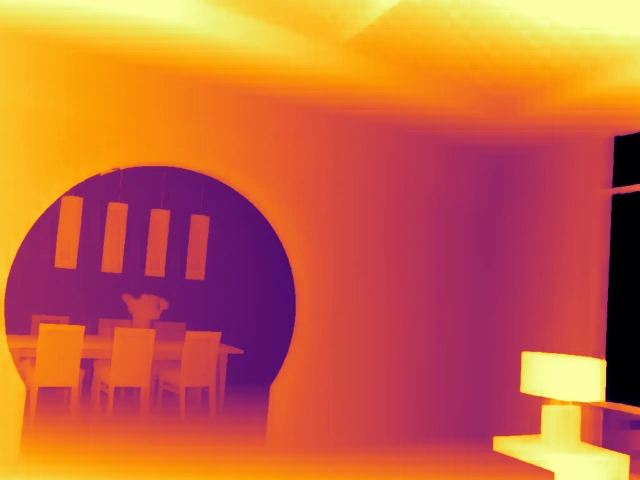
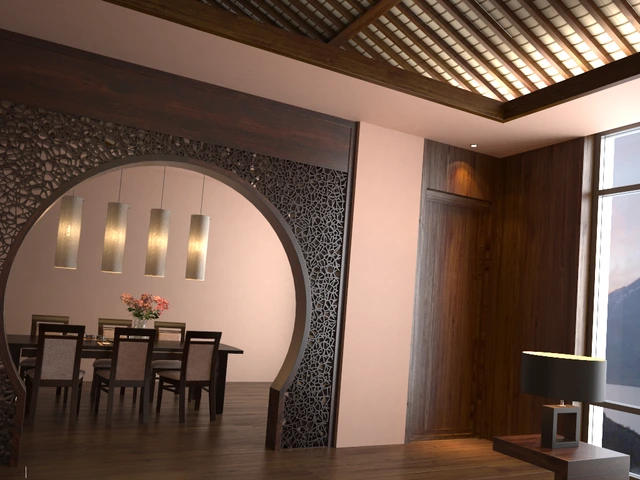 PhotoDepth
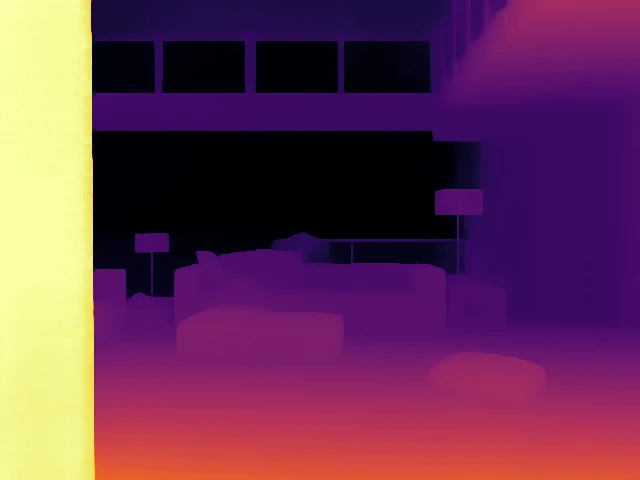
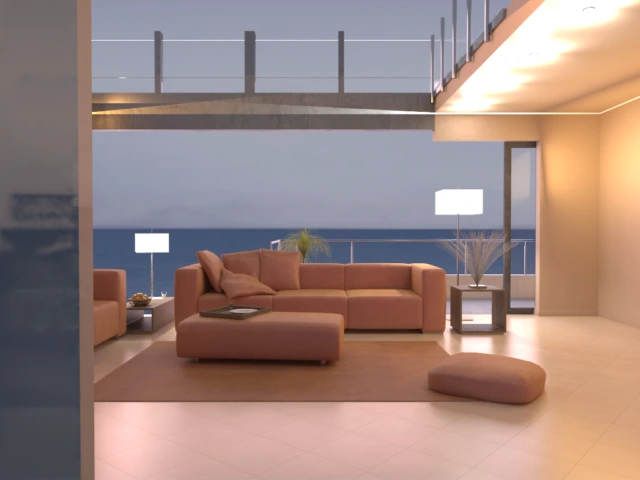 PhotoDepth
Point clouds from predicted depth · drag to orbit, scroll to zoom
Image Restoration / Super-resolution
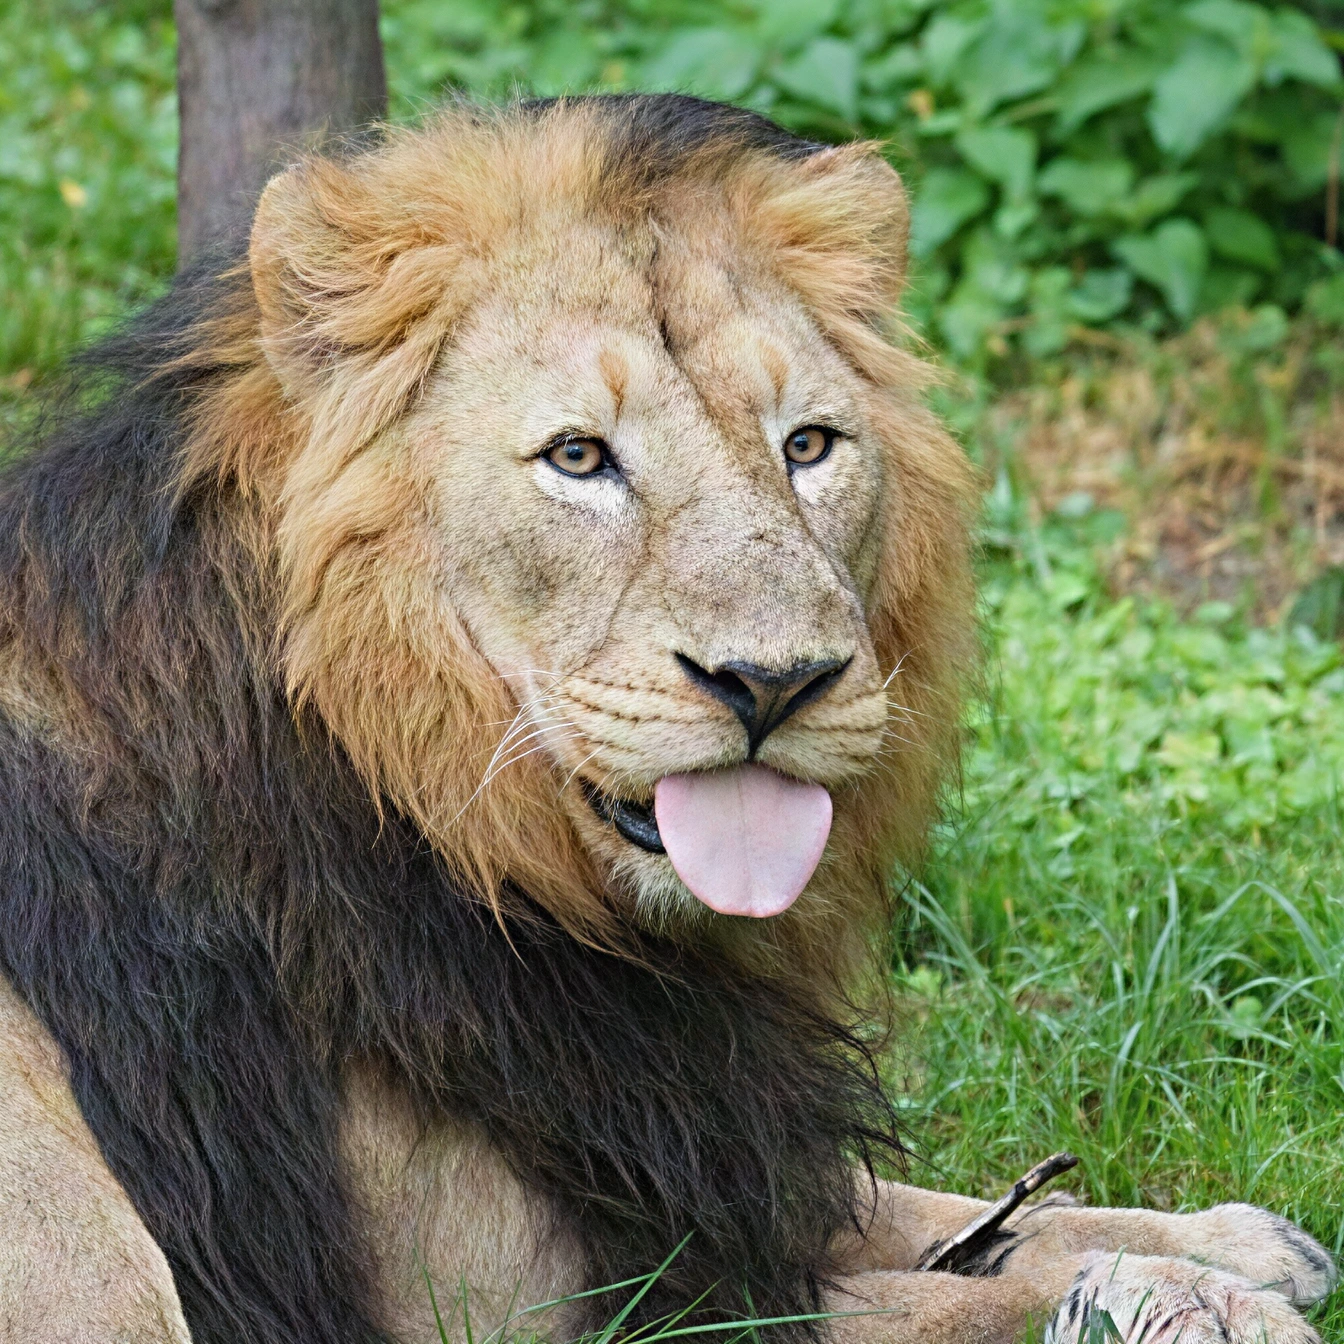
 InputIris-3B
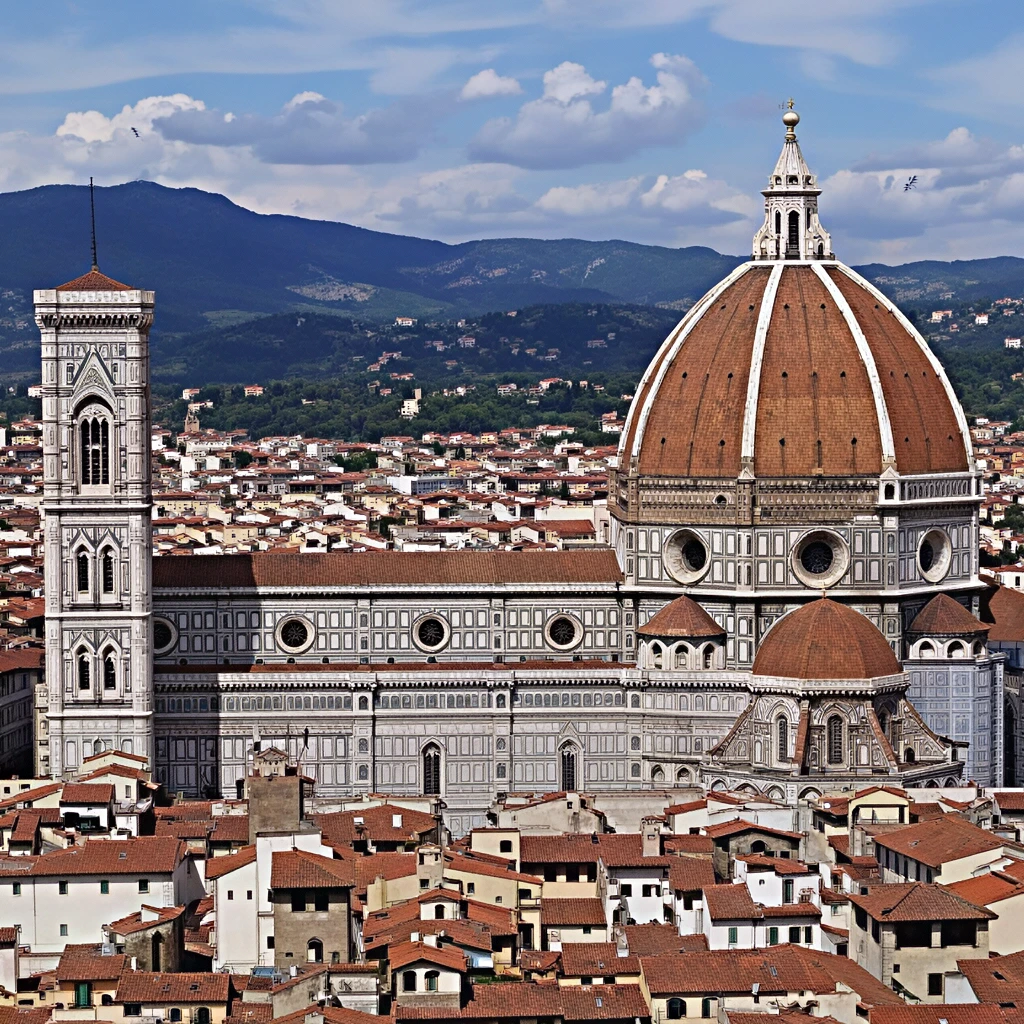
 InputIris-3B
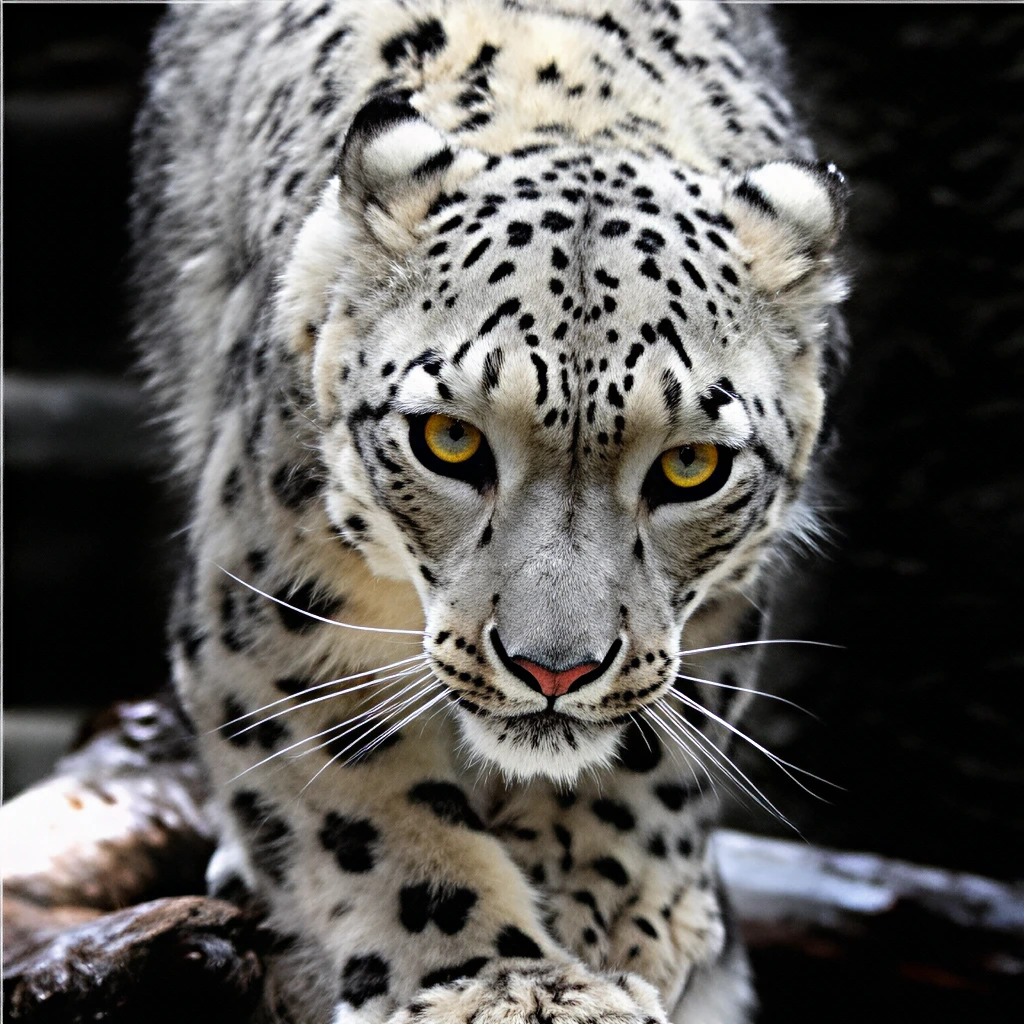
 InputIris-3B
 InputIris-3B
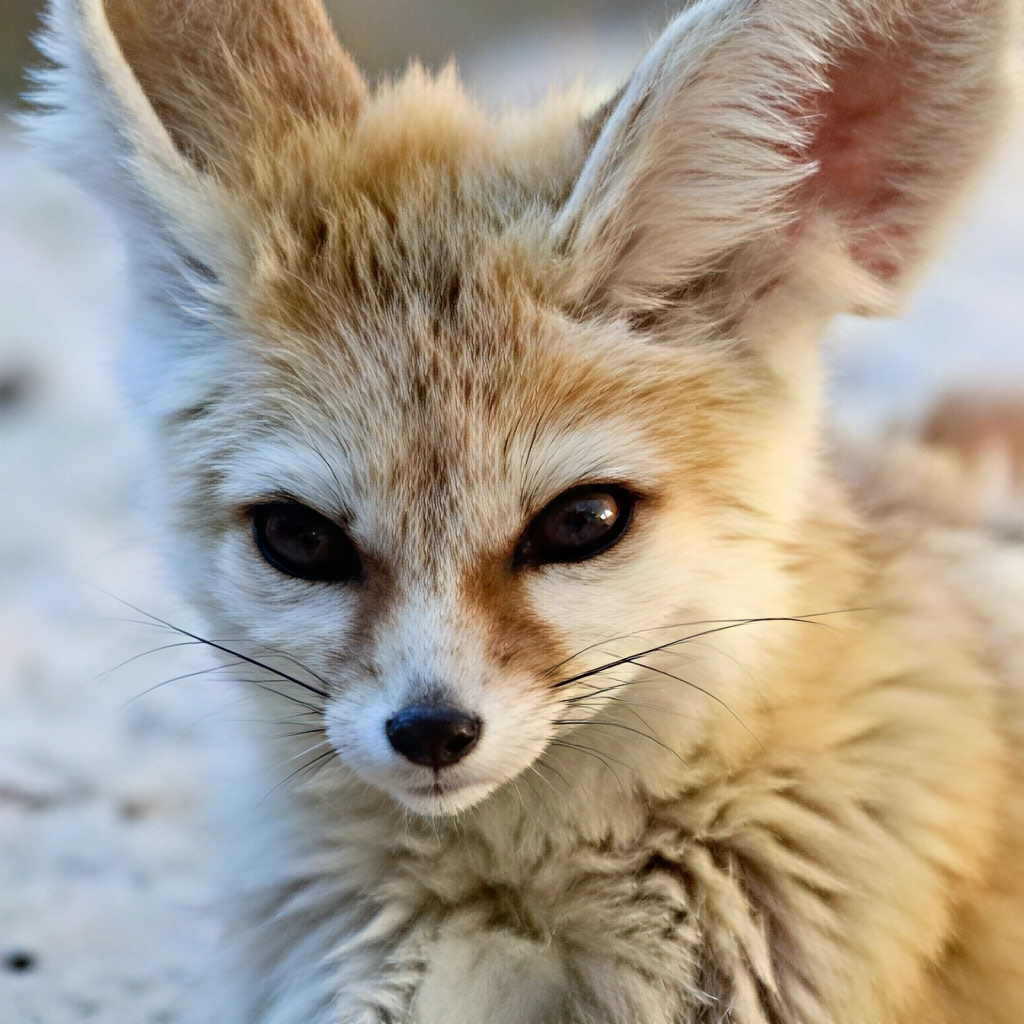
 InputIris-3B
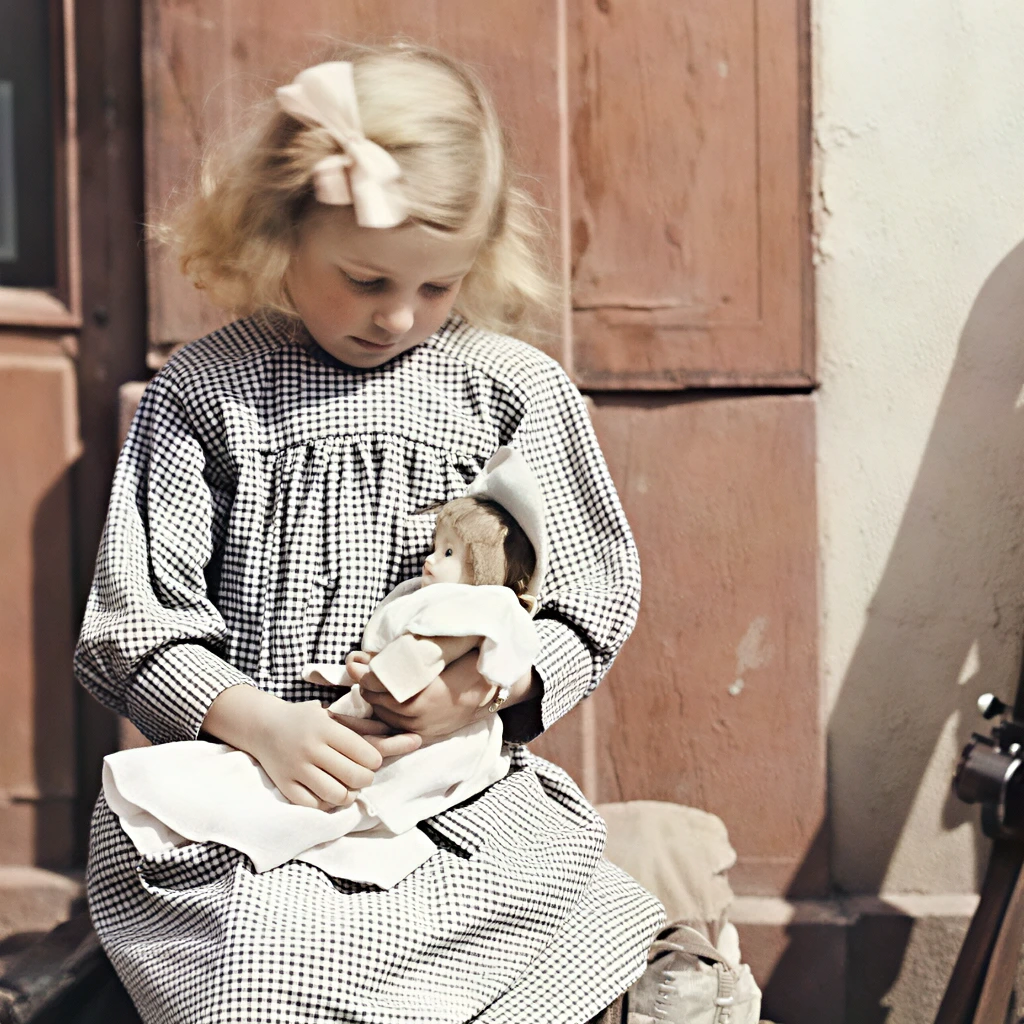
 InputIris-3B
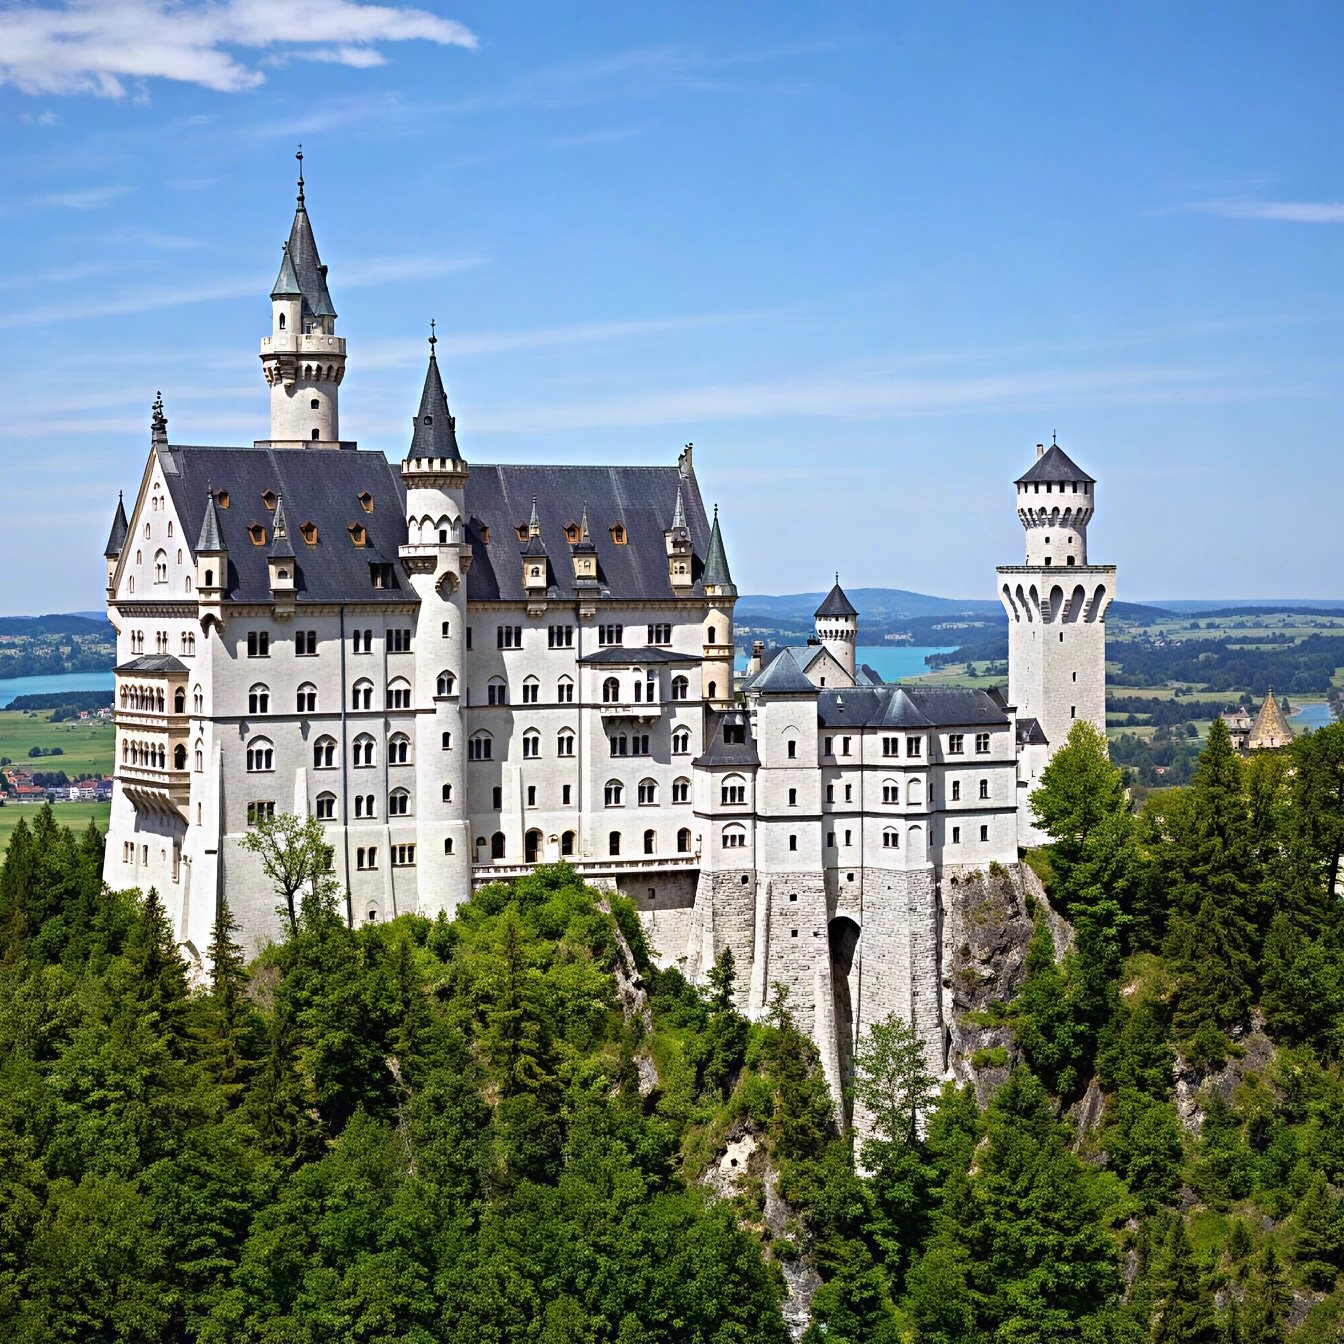
 InputIris-3B
 InputIris-3B
 InputIris-3B
Cite this work
@techreport{licai2026iris,
  title       = {Iris-3B: Going Beyond the Latent with Pixel-Space
                 Diffusion Training, Conversion and Fine-Tuning},
  author      = {Li Cai, Hanqiu and Garabito, Chema},
  institution = {Speridlabs},
  year        = {2026}
}